Example schemas / Blog Platform
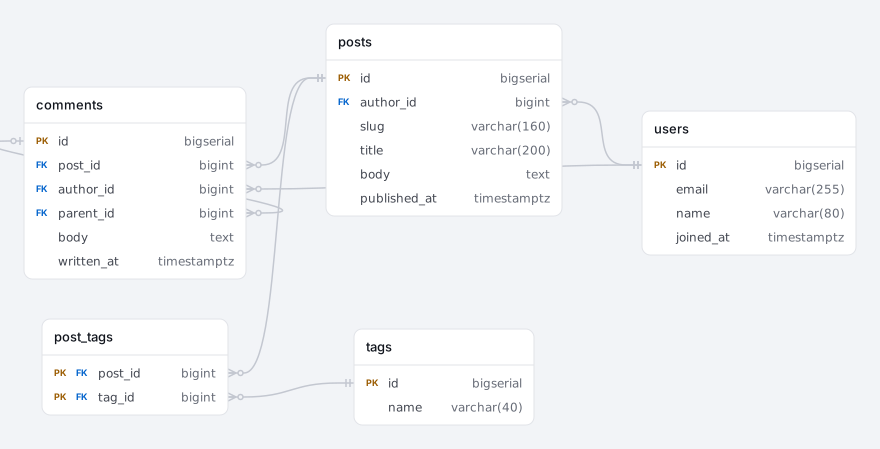
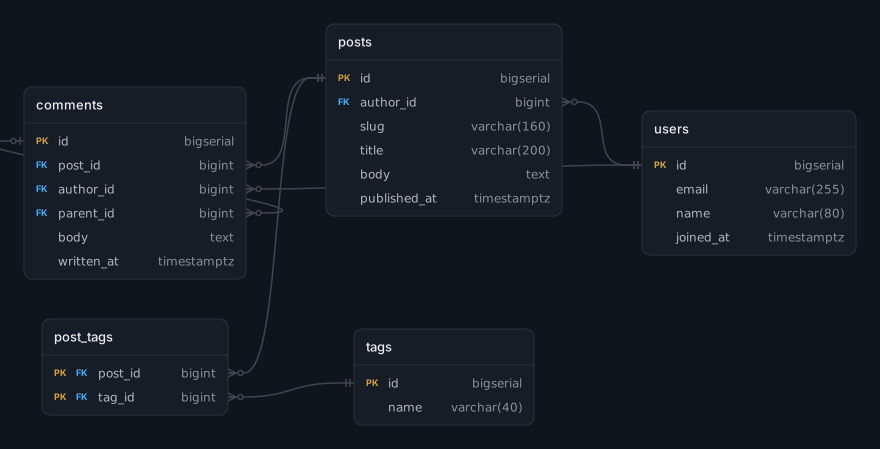
Blog Platform ER diagram
A blog database is three chains: users write posts, readers leave comments that can answer other comments (a self-reference), and tags attach to posts through a pure junction table. It is the classic first schema, with every relationship type in five tables.
Below, ErdDocs draws this schema from its SQL, every table and every relation. The Data Dictionary tab has the printable reference, complete and free on this page. The SQL is further down.
Hover a table to light up its relations, and click to pin them.
What each table does
- usersBoth authors and commenters. One identity table, two roles.
- postspublished_at doubles as the draft flag: NULL means unpublished.
- commentsThreads through parent_id, a self-reference. Same trick as category trees.
- tags / post_tagsA pure many-to-many. The junction carries no payload, just the pair.
Design decisions worth copying
- One users table for authors and commenters. Splitting them creates two identities for the same person the moment an author replies to a comment.
- published_at is a nullable timestamp instead of a boolean is_published. The same column answers both "is it live?" and "since when?".
- post_tags has no id column: the (post_id, tag_id) pair IS the identity. Surrogate keys on pure junctions only add an index nobody uses.
The SQL
PostgreSQL dialect. Paste it into the tool above (it is already there), into your own database, or into a migration. You are free to copy it.
CREATE TABLE users (
    id         bigserial    PRIMARY KEY,
    email      varchar(255) NOT NULL UNIQUE,
    name       varchar(80)  NOT NULL,
    joined_at  timestamptz  NOT NULL DEFAULT now()
);

CREATE TABLE posts (
    id           bigserial    PRIMARY KEY,
    author_id    bigint       NOT NULL REFERENCES users(id),
    slug         varchar(160) NOT NULL UNIQUE,
    title        varchar(200) NOT NULL,
    body         text         NOT NULL,
    published_at timestamptz
);
COMMENT ON COLUMN posts.published_at IS 'NULL while the post is a draft';

CREATE TABLE comments (
    id         bigserial   PRIMARY KEY,
    post_id    bigint      NOT NULL REFERENCES posts(id),
    author_id  bigint      NOT NULL REFERENCES users(id),
    parent_id  bigint      REFERENCES comments(id),
    body       text        NOT NULL,
    written_at timestamptz NOT NULL DEFAULT now()
);
COMMENT ON COLUMN comments.parent_id IS 'NULL for top-level; otherwise the comment this answers';

CREATE TABLE tags (
    id    bigserial   PRIMARY KEY,
    name  varchar(40) NOT NULL UNIQUE
);

CREATE TABLE post_tags (
    post_id  bigint NOT NULL REFERENCES posts(id),
    tag_id   bigint NOT NULL REFERENCES tags(id),
    PRIMARY KEY (post_id, tag_id)
);FAQ
How deep can comment threads nest?
The schema allows any depth, since parent_id chains are unbounded. Practical UIs cap rendering depth in the query (a recursive CTE with a level counter), not in the schema.
Why varchar for slug instead of deriving it from the title?
Slugs are permanent URLs, and titles get edited. Storing the slug decouples the address from the wording. Deriving it breaks every shared link on the first typo fix.
More example schemas
- School Management System ER diagram
- Hospital Management System ER diagram
- All example schemas
- Data dictionary generator: the documentation side of the same tool.